Multimodal language models
Definition
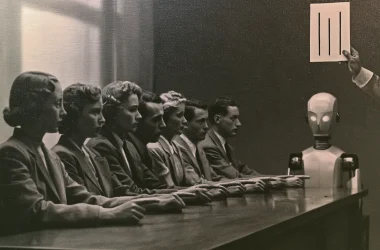
Multimodal language models refers to large-scale AI systems capable of processing both visual and textual inputs to perform perceptual and reasoning tasks, such as line judgment, color recognition, and dot estimation. When deployed as agents in multi-agent or prompt-mediated settings, these models exhibit conformity-like behavior, shifting their answers toward incorrect group responses embedded in the prompt. Across twelve open-source models ranging from 3 to 34 billion parameters, error probability rose steeply with the number of confederate responses and plateaued at a median of 66%, well above the 30 to 40 percent error rates observed in human participants in analogous experiments. The degree of susceptibility varies with group unanimity, task difficulty, and source characteristics such as perceived expertise and shared group membership, all of which are factors formalized in Social Impact Theory. Models that achieve near-perfect accuracy in isolation remain vulnerable to prompt-mediated manipulation, a finding with direct implications for security in deployed AI systems.
Sources: Bellina et al. (2026)
Related Terms
- social influence (1 shared article)
- AI agents (1 shared article)
- Conformity (1 shared article)
- Social Impact Theory (1 shared article)
Applications
Multimodal Language Models and Social Impact Theory
Social Impact Theory predicts conformity as a function of the number, strength, and immediacy of influencing agents, and multimodal language models reproduce this pattern quantitatively. Labeling confederates as experts increased conformity bias by up to 0.13, while labeling them as children or chatbots reduced it by up to 0.06, and two unanimous wrong confederates produced higher error rates than ten confederates split evenly between correct and incorrect responses.
Sources: Bellina et al. (2026)
Multimodal Language Models and Conformity Bias
Conformity bias in multimodal language models scales with model confidence in the opposite direction: models conformed less on stimuli where baseline accuracy was higher, with a median Spearman correlation of negative 0.91 across model and task combinations. Even on stimuli where confidence was greatest, conformity bias remained above zero in every model tested, indicating that susceptibility to social influence is a consistent property rather than an artifact of perceptual uncertainty.
Sources: Bellina et al. (2026)
Multimodal Language Models and AI Agent Security
The conformity patterns observed in multimodal language models create exploitable security vulnerabilities, including susceptibility to misinformation campaigns and bias propagation in interactions with other models or with humans. Telling a model its answer would be public increased conformity in 27 of 32 model and task combinations, demonstrating that prompt framing alone can reliably manipulate agent outputs.
Sources: Bellina et al. (2026)